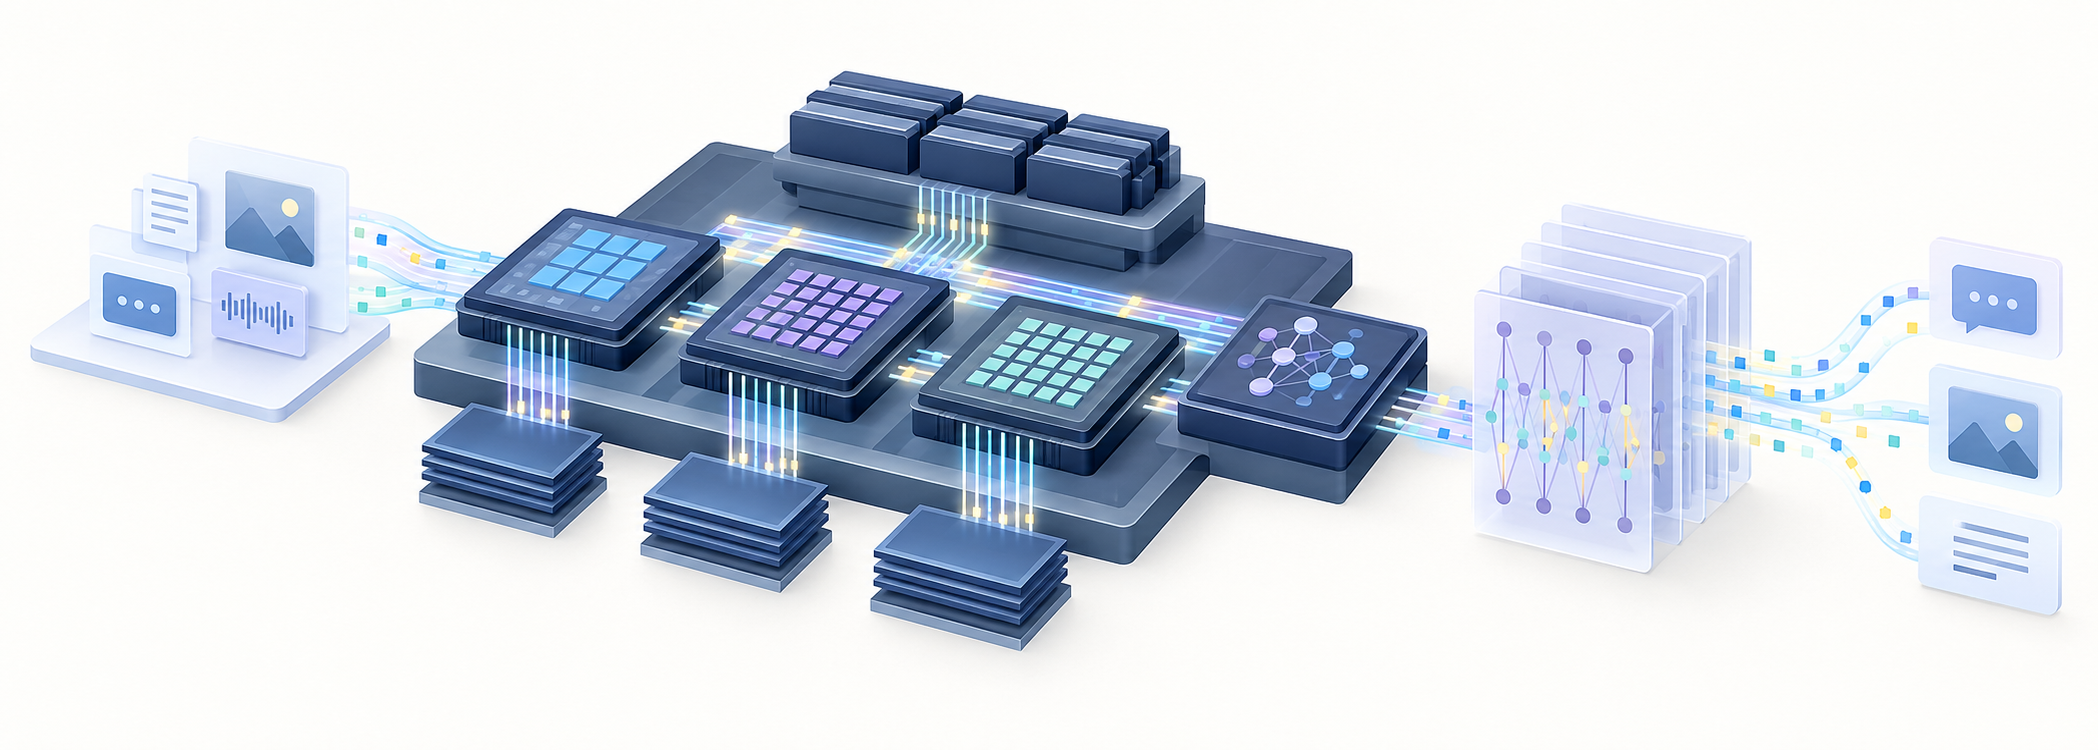
We build heterogeneous systems for emerging AI workloads. Our work spans LLM training and inference, CPU–GPU cooperation, Intel AMX, billion-scale approximate nearest-neighbor and vector search, on-device AI, and specialized accelerators. By co-designing algorithms, runtimes, memory movement, and hardware scheduling, we make diverse compute engines work as one efficient system.
AI Systems & Heterogeneous Computing